
Aspect-Based Sentiment Analysis on Financial News
Fine-tuned RoBERTa-base for entity-level sentiment on 10,686 financial headlines, reaching 86.67% accuracy and 100% recall on negative sentiment with leakage-free, title-based splits.
Role
NLP Engineer & Deep Learning Researcher
Client
Academic Project - Natural Language Processing Course
Team
3-person Team
Timeline
2 months • 2025
Problem
One headline often carries opposite sentiment toward different companies, the labels are heavily skewed toward neutral, and naive row-based splits leak headlines between train and test.
Solution
Framed the task as entity-conditioned classification, split on unique titles to prevent leakage, and fine-tuned RoBERTa-base with weighted loss, label smoothing and early stopping on F1-macro.
Impact
86.67% accuracy and 93% F1-macro at 96.25% mean confidence, with every negative headline caught and inference under 50 ms on GPU.
Skills & Tools
Skills Applied
Tools & Software
Project Overview
This project fine-tunes RoBERTa-base for Aspect-Based Sentiment Analysis (ABSA) on financial news headlines (SEntFiN v1.1). Unlike document-level sentiment, ABSA scores sentiment toward each entity in a headline — so "Gold shines on seasonal demand; Silver dull" yields Gold: positive, Silver: negative. The model reaches 86.67% accuracy at 96.25% average confidence, with 100% accuracy on negative sentiment — the critical class for financial risk monitoring.
Dataset
SEntFiN v1.1 provides 10,686 headlines with entity-level annotations (14,409 aspect-sentiment pairs, roughly 1.35 entities per headline). Headlines average 24 tokens, so a 40-token max length covers 99%+ of the data. The class distribution skews heavily toward neutral, requiring weighted loss and F1-macro evaluation rather than raw accuracy.
Methodology
Anti-leakage splitting — because one headline can carry multiple entities with different sentiments, splitting is done on unique titles (80/20) so no headline appears in both train and test. This yields 8,548 training headlines (11,493 pairs) and 2,138 test headlines (2,916 pairs). Multi-entity headlines are then flattened into one training sample per entity.
Model — RoBERTa-base (125M parameters, fully fine-tuned) with input format [CLS] entity [SEP] sentence [SEP] and a 3-class head (negative / neutral / positive).
Regularization — to prevent overfitting on a small, imbalanced dataset: weighted cross-entropy (negative 1.26, neutral 0.87, positive 0.95), label smoothing (0.05), dropout (0.3), L2 weight decay (0.01), and gradient clipping (1.0).
Training — AdamW (lr 2e-5) with warmup and linear decay, batch size 128, up to 15 epochs, early stopping (patience 5 on validation F1-macro).
Results
Test set (2,916 samples): 86.67% accuracy, 93% F1-macro, 96.25% mean confidence.
Per class:
- Negative — 100% accuracy (98%+ confidence), essential for risk monitoring.
- Positive — 80%; the single miss was a TCS hiring announcement read as neutral.
- Neutral — 80%; the single miss was "Asian Paints maintains market share" read as positive.
Every error sits on the neutral/positive boundary (announcement- and "maintains"-style phrasing); there is no positive/negative confusion. All predictions exceed 90% confidence, so confidence-threshold filtering is viable in production.
Deployment Notes
Trained in under 45 minutes on an RTX 3060 (~8 GB VRAM). The packaged model (~500 MB, including tokenizer and label maps) runs inference in under 50ms on GPU, supporting entity-level sentiment tracking, negative-sentiment risk alerts, and sector-level aggregation.
Key Takeaways
- Title-based splitting is essential for ABSA — row-based splitting leaks entity context and inflates metrics.
- Weighted loss and F1-macro are non-negotiable for imbalanced data; per-class metrics reveal what accuracy hides.
- General RoBERTa pre-training is enough for strong financial-domain performance — no finance-specific pre-training needed.
- Perfect negative-sentiment detection plus high confidence makes the model well suited to financial risk monitoring.
Future Work
Expand beyond Indian-market English headlines to global and multilingual sources, add temporal splits for trend analysis, and evaluate finance-specific models (FinBERT) with attention-based interpretability.
Source: aspect-based-financial-sentiment · Course: Natural Language Processing, Hasanuddin University, 2025
Project Metrics
86.67% accuracy on test set
96.25% average prediction confidence
14,409 aspect-sentiment pairs processed
125M parameter RoBERTa-base fine-tuned
100% accuracy on negative sentiment detection
Credits & Acknowledgments
SEntFiN v1.1 Dataset
Hugging Face Transformers library
PyTorch deep learning framework
NVIDIA CUDA for GPU acceleration
Project Tags
Related Projects
View all projects →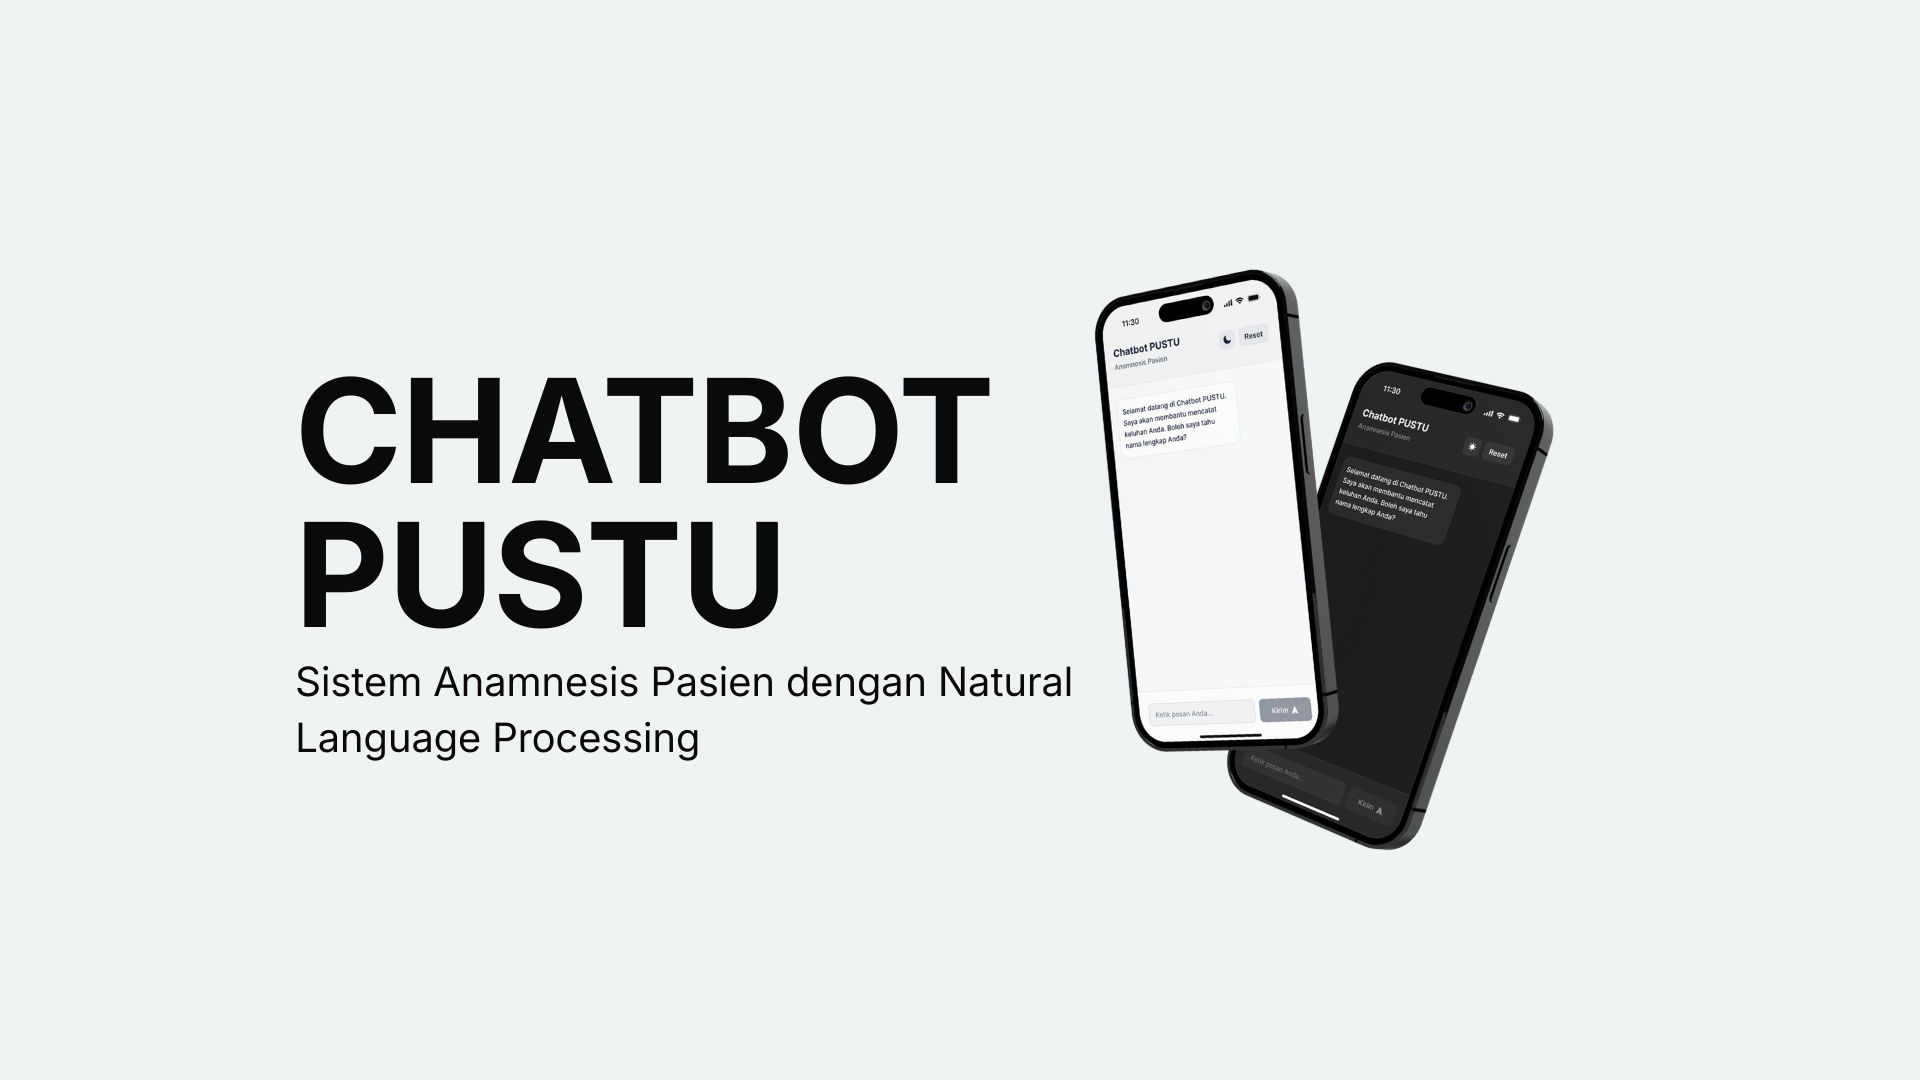
Medical Anamnesis Chatbot with NLP (Chatbot PUSTU)
Indonesian medical anamnesis chatbot for Puskesmas reaching 92.61% intent accuracy across 14 classes, trained on 14,000 samples generated with Gemini 2.0 Flash and a custom preprocessing and NER pipeline built from scratch.
Urban Complaint Pattern Mining on NYC 311 Data (21M+ Records)
Data mining of 21.3M NYC 311 requests that found a six-complaint building 'syndrome' (mean lift 8.48) and validated it against 11M inspection records: 12-44x higher violation rates.
ICONNET Finance Dashboard
Next.js 16 · React 19 · TypeScript
ICONNET Finance Dashboard - OPEX, Cash Advance & Contract Monitoring
Internal finance dashboard for PLN Icon Plus that replaced spreadsheet-based reporting with four modules (OPEX monitoring, cash-advance tracking, outsourced-staff contract budgets, and vehicle monitoring) on a Next.js + Express + PostgreSQL stack, hardened after a full penetration test.