
E-Commerce Trust Simulation with LLM-Powered Agents
Agent-based simulation of 7,580 Llama 3.1-powered agents showing fake-review campaigns lift conversion of low-quality products by 54-72 percentage points (Chi-Square 121-177, p < 0.0001).
Role
Simulation Engineer & Data Scientist
Client
Academic Project - Simulation and Modeling Course
Team
3-person Team
Timeline
2 weeks • 2025
Problem
The real effect of coordinated fake reviews on purchase decisions is hard to measure ethically, and rule-based agents cannot read or write reviews the way people do.
Solution
Built a MESA marketplace with 1,200 genuine reviewers, 530 fake reviewers and 6,000 shoppers across three personas, with every review and purchase decision generated by a local Llama 3.1 8B model through Ollama.
Impact
Targeted low-quality products went from 0% to 54-72% conversion; even skeptical shoppers moved +40pp. Running the LLM locally removed API cost entirely.
Skills & Tools
Skills Applied
Tools & Software
Project Overview
An agent-based modeling (ABM) study simulating an e-commerce marketplace with 7,580 autonomous agents to quantify how coordinated fake-review campaigns manipulate consumer trust and conversion. Built with the MESA framework and local Llama 3.1 8B (via Ollama) for realistic review and purchase behavior, this was the final project for the Simulation and Modeling course at Hasanuddin University.
Research Questions
- RQ1 — How much does a fake-review campaign raise conversion for low-quality products?
- RQ2 — Which consumer persona (Impulsive, Careful, Skeptical) is most vulnerable?
Key Findings
| Research Question | Key Result |
|---|---|
| RQ1: BudgetBeats (Low Quality) | 0% to 54% conversion (+54pp, Chi-Square = 121.30, p less than 0.0001) |
| RQ1: ClearSound (Low-Medium) | 0% to 72% conversion (+72pp, Chi-Square = 177.35, p less than 0.0001) |
| RQ2: Most Vulnerable | Careful: +95pp, Impulsive: +92.5pp |
| RQ2: Least Vulnerable | Skeptical: +40.44pp (2.3x less vulnerable) |
Simulation Architecture
Built on MESA with 5 headphone products (quality tiers from 4.25 to 9.25 out of 10), a random-activation scheduler, and per-iteration data collection. Two low-quality products — BudgetBeats (4.25/10) and ClearSound (5.25/10) — were targeted by fake reviews; three higher-quality products acted as controls.
Agent population (7,580):
- 1,200 genuine reviewers — critical, balanced, and lenient personalities
- 530 fake reviewers — coordinated burst (80 reviews) then maintenance (450 reviews)
- 6,000 shoppers — Impulsive (reads 3 reviews), Careful (10), Skeptical (15)
LLM Integration
Llama 3.1 8B runs locally via Ollama with dynamic context windows (2,048–8,192 tokens) and role-specific temperature (0.3 shoppers, 0.6 genuine reviewers, 0.7 fake reviewers) — at zero API cost. Genuine-reviewer prompts are quality-aware and personality-driven; fake-reviewer prompts always give 5 stars with varied openings to avoid detection patterns; shopper prompts encode persona-specific decision logic.
Experimental Design
Attacks follow a burst + maintenance timeline: baseline (iterations 1–3, genuine reviews only), burst (4–5, 160 fake reviews), then adaptive maintenance (6–20) that scales fake volume to defend the rating (aggressive / moderate / normal). Reviews, transactions, and per-product metrics are exported to CSV each iteration for independent analysis.
RQ1: Fake-Review Impact
Chi-Square tests on the two targeted products:
| Product | Baseline Conv | Attack Conv | Increase | Chi-Square | p-value | Cramér's V |
|---|---|---|---|---|---|---|
| BudgetBeats | 0.00% | 54.17% | +54.17pp | 121.30 | less than 0.0001 | 0.636 |
| ClearSound | 0.00% | 71.67% | +71.67pp | 177.35 | less than 0.0001 | 0.769 |
Both results are extremely significant (p under 0.0001) with large effect sizes (Cramér's V above 0.6). Control products moved only +3–4pp from natural variation, confirming the jumps are caused by the campaign rather than noise.
RQ2: Persona Vulnerability
| Rank | Persona | Baseline | Attack Period | Impact |
|---|---|---|---|---|
| 1 | Careful | 0.0% | 95.0% | +95.00pp |
| 2 | Impulsive | 0.0% | 92.5% | +92.50pp |
| 3 | Skeptical | 0.0% | 40.4% | +40.44pp |
ANOVA confirms significant differences between personas (F = 540.28, p under 0.0001). Counterintuitively, the Careful persona is most vulnerable (+95pp): reading more reviews backfires when fake reviews dominate the sample. The Skeptical persona — which checks 15 reviews and watches for burst patterns — is 2.3x more resistant (+40pp).
Key Contributions
- First simulation to quantify fake-review conversion lift (+54–72pp) with publication-grade statistical rigor.
- Novel vulnerability finding: deeper-but-naive analysis (Careful) is riskier than skeptical pattern-checking.
- Demonstrates local-LLM agent-based modeling for realistic natural-language behavior at zero API cost.
Practical Implications
- Platforms — flag sudden rating jumps and review bursts; educate the most-vulnerable user segments.
- Consumers — a skeptical mindset and attention to review timing offer 2.3x more protection than trusting star ratings alone.
Performance & Reproducibility
LLM inference averages 1.8s per review (roughly 1,730 reviews in ~52 minutes, ~8 GB RAM); a full 20-iteration run takes ~4–6 hours on consumer hardware, with a fixed random seed (42) and CSV exports for reproducibility.
Repository: fake-review-abm-llm · Course: Simulation and Modeling, Hasanuddin University, 2025
Project Metrics
7,580 autonomous agents (1,200 genuine + 530 fake reviewers + 6,000 shoppers)
1,730 LLM-generated reviews (1,200 genuine + 530 fake)
+54-72pp conversion rate increase in targeted products
Chi-Square = 121.30-177.35, p less than 0.0001 statistical significance
100% API cost elimination via local Llama 3.1 8B deployment
Credits & Acknowledgments
MESA Framework for agent-based modeling
Ollama for local LLM inference
Llama 3.1 8B by Meta AI
SciPy for statistical testing
Project Tags
Related Projects
View all projects →
Urban Complaint Pattern Mining on NYC 311 Data (21M+ Records)
Data mining of 21.3M NYC 311 requests that found a six-complaint building 'syndrome' (mean lift 8.48) and validated it against 11M inspection records: 12-44x higher violation rates.
ICONNET Finance Dashboard
Next.js 16 · React 19 · TypeScript
ICONNET Finance Dashboard - OPEX, Cash Advance & Contract Monitoring
Internal finance dashboard for PLN Icon Plus that replaced spreadsheet-based reporting with four modules (OPEX monitoring, cash-advance tracking, outsourced-staff contract budgets, and vehicle monitoring) on a Next.js + Express + PostgreSQL stack, hardened after a full penetration test.
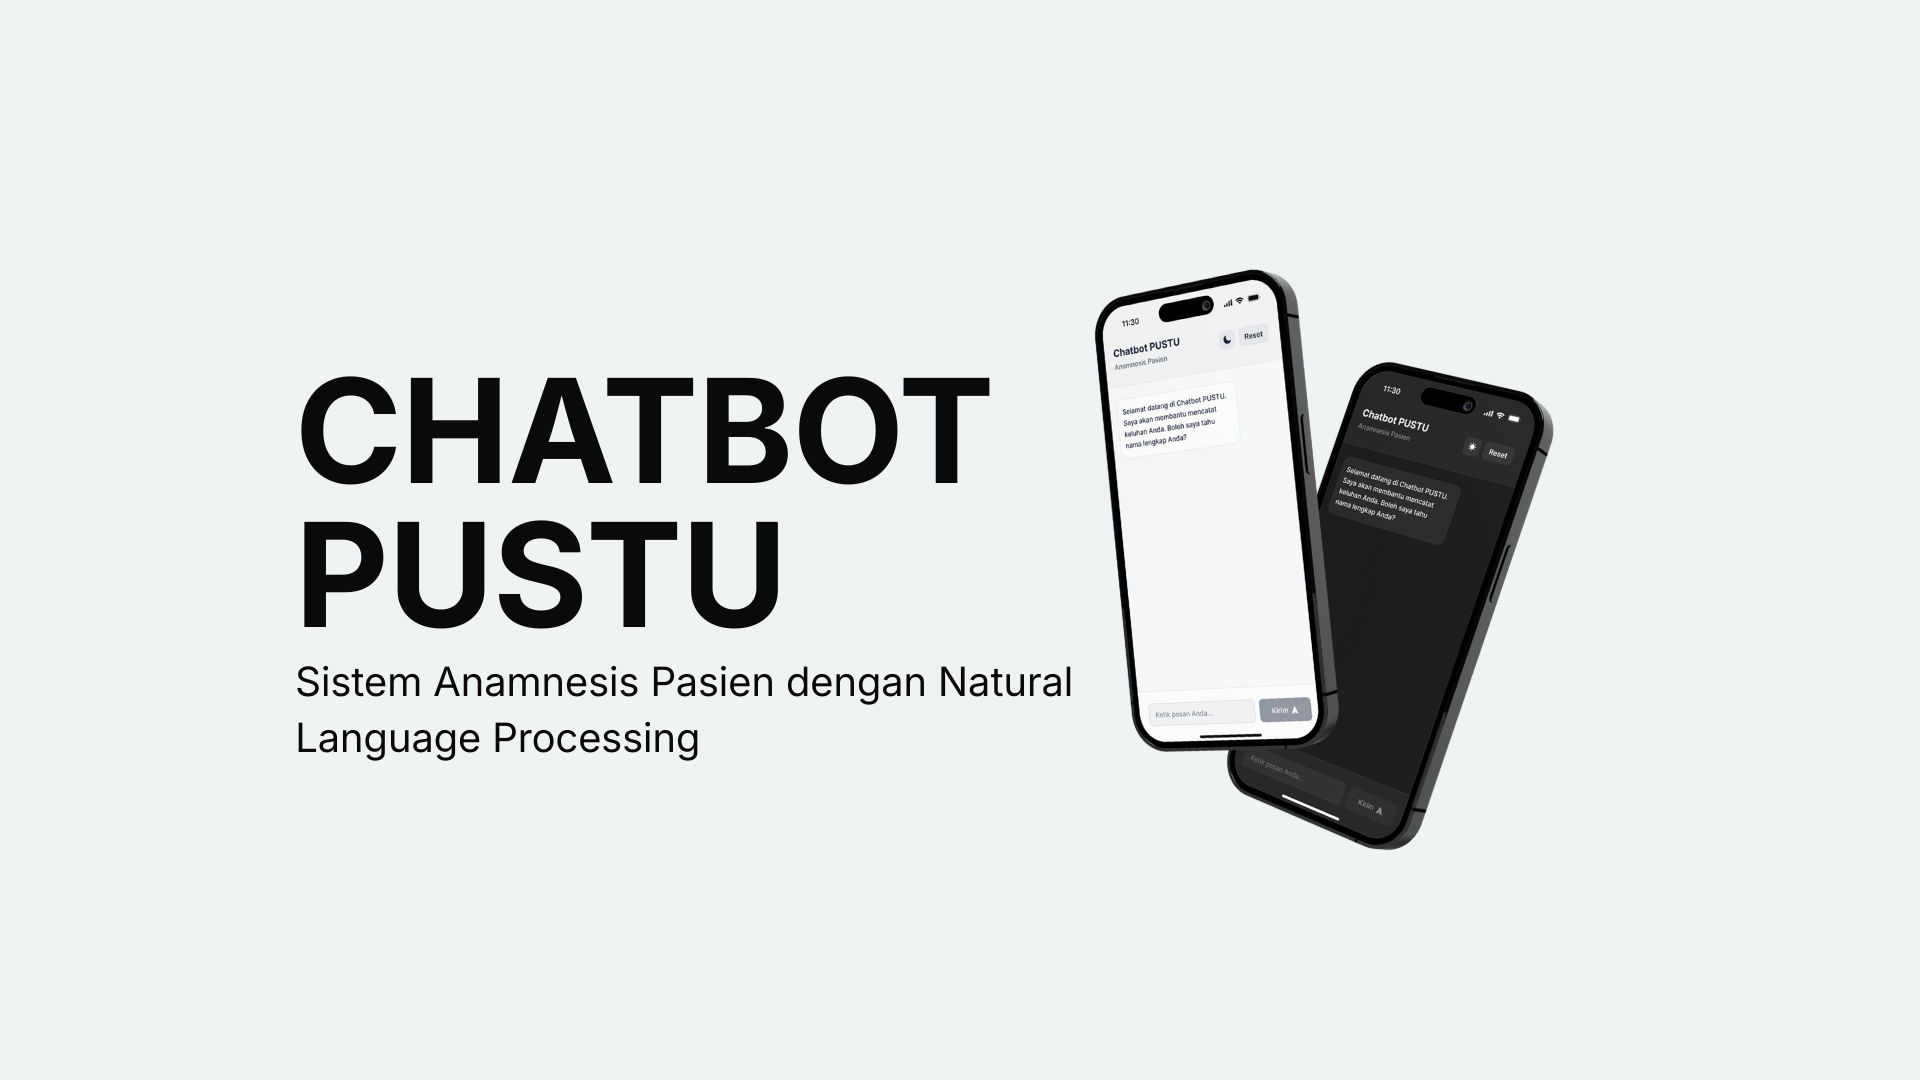
Medical Anamnesis Chatbot with NLP (Chatbot PUSTU)
Indonesian medical anamnesis chatbot for Puskesmas reaching 92.61% intent accuracy across 14 classes, trained on 14,000 samples generated with Gemini 2.0 Flash and a custom preprocessing and NER pipeline built from scratch.